 Opportunity score: 59 out of 100 — Mixed
Dropbox for Agents
Lets your AI coding agents pass notes to each other, so none starts from zero.
Published · Last assessed · Methodology v5.1 · How ideas are researched and assessed
Problem in brief
Developers increasingly run more than one AI coding agent across the same projects and machines. What an agent works out — a debugging conclusion, a schema decision, a note for whoever picks the work up next — stays in that vendor's conversation log, so the next agent starts from zero. Vendor issue-tracker reports describe memory as individual-only, with context built in one surface invisible to another and no supported way to share it. Today people cope by scrolling back through chat history to copy snippets, pasting findings into notes apps the agents cannot read back, or hacking shared state into whatever file both tools happen to touch.
- Who has this problem
- Solo developers and small teams running two or more AI coding agents (e.g. Claude Code, Cursor, Codex CLI) across the same projects and machines
- How they cope today
- Manually scrolling chat history to copy snippets, human-oriented notes tools, or abusing a package cache as a message board
- What it costs them
- Lost time, copy/paste errors, and knowledge tied to a single tool rather than travelling with the user
- Opportunity explored
- Dropbox for Agents, described below
The problem in detail
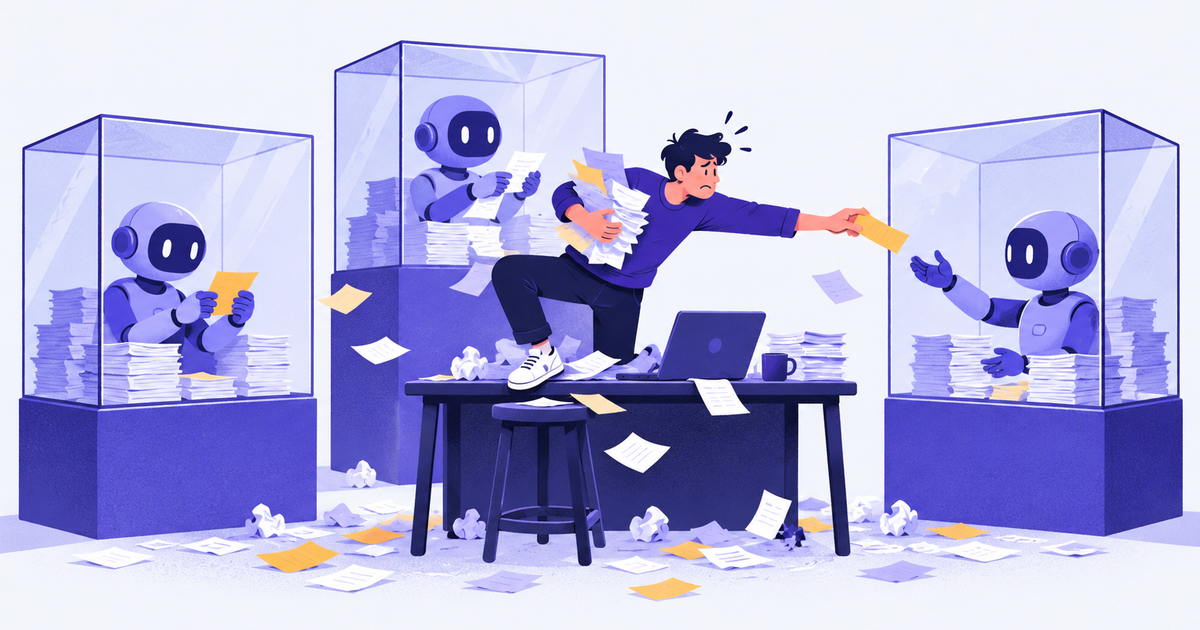
Everything an agent produces of lasting value — a debugging conclusion, a schema decision, a handoff note for the next agent — dies in the vendor's conversation log. Developers scroll back through chat history to copy snippets by hand, paste findings into human-oriented notes apps that agents can't read back, or hack shared state into whatever store both tools happen to touch (a package cache, a scratch file, a pinned issue). The knowledge belongs to the tool, not the person, and the second agent starts from zero.
Proposed product
A single-binary MCP server that gives every agent the same four verbs — write, read, list, subscribe — against a plain Markdown store in a Git repo the developer already owns. Each entry is a file with YAML frontmatter (author agent, project, tags, optional to: recipient) and a stable slug URL. Any MCP-speaking agent can drop a note; any other agent, or the developer via `drop read` in the terminal, picks it up. Because the backing store is Markdown in Git, the knowledge survives switching agents, is diffable, greppable, and reviewable in a pull request, and needs no hosted service or account.
Why now
Developers now run several AI coding agents on the same projects, and vendor issue trackers in March and June 2026 confirm that each tool's memory stays private to that tool, with no supported way to share it. Free Markdown memory projects and a paid incumbent already exist, so the opening is making cross-tool sharing actually work rather than the idea itself.
Smallest useful version
Ship the MCP server plus CLI with two namespaces only: `notes/` (durable knowledge, append-and-edit) and `inbox/` (agent-to-agent messages, read-once then archived). Install is one command, config is one path to a Git repo. Success signal: developers add it to more than one agent's MCP config and it accumulates entries written by one agent and read by another within the first week — the cross-agent read is the whole test.
Potential ways to charge
- Open source — £0: the single-binary server and command-line tool, keeping notes in a Git repository you already own (free is the norm here: the evidence lists several free open-source equivalents)
- Hosted sync — £5 per month: backup and sync across machines without running your own Git remote (mirrors the incumbent's paid hosted tier, whose price the evidence does not show; typical for comparable tools)
- Team — £8 per seat per month: shared team stores, control over which agents and people write where, and agent-written notes reviewed in pull requests (typical for comparable tools; no evidence-based anchor exists)
- Self-hosted business — £2,000 per year: a private build with single sign-on and policy controls for firms that must keep agent knowledge in-house (typical for comparable tools; no evidence-based anchor exists)
Routes to early customers
- Comment on and link the existing vendor issue-tracker threads about shared team memory and cross-surface context, where people with the exact problem are already gathered
- Publish a write-up specifically on the documented failure mode — two clients connected to the same memory server sharing nothing — with the fix, aimed at the practitioners already blogging this scenario
- List in MCP server directories and the curated agent-memory lists where the competing OSS projects are already discovered
- Approach small teams running mixed Claude Code / Cursor / Codex CLI setups directly, offering to set up cross-client scoping for free in exchange for a week of usage data
Main risks
- Direct competition: an established Markdown-and-Git MCP memory server already occupies nearly this exact position, with Obsidian compatibility and a hosted tier, so a new entrant must win on something narrower than 'notes in Git'.
- Commoditisation: the evidence lists several free OSS projects doing markdown-based cross-agent memory and handoffs, making paid conversion doubtful.
- The riskiest assumption is untested — agents may not call write unprompted at useful moments, leaving the store either empty or full of chatter; if the human must say 'save this', it is a slower notes app.
- No demand signal was found in paid-work or search-volume sources, so willingness to pay anything is unevidenced.
- Cross-client scoping is itself the hard part; if project/repo keying differs between clients the product fails in exactly the way the evidence says others already fail.
Questions to test first
- Instrument a prototype and measure the unprompted write rate: over a week of real work across two agents, how many durable conclusions get written without the human asking?
- Run the same store against two different MCP clients on one project and verify both resolve identical scope — reproduce the documented failure mode, then prove you fix it.
- Install alongside the incumbent Markdown/Git MCP memory server for five developers and ask which they keep after a fortnight, and why.
- Post the cross-client scoping write-up and count installs and cross-agent reads, not stars.
- Ask ten users of free OSS agent-memory tools what, if anything, would make them pay — before building any hosted tier.
Evidence and sources
The sources this assessment is based on. Evidence level: Indicative, counted from these sources as described in how ideas are assessed. Findings are what a source shows; anything the research only inferred is marked as an inference.
Research findings
SupportsGitHub issue (anthropics/claude-code #70072) · 23 June 2026
Shows: issue-tracker report of cross-surface/multi-machine handoff gap
A user reports that context built up in Claude Code (CLAUDE.md + auto-memory) is invisible to Claude Desktop and vice versa, with no supported way to give both surfaces the same persistent context across machines. Confirms the 'second agent starts from zero' symptom across surfaces and machines, the exact customer described.
SupportsGitHub issue (anthropics/claude-code #38536) · 25 March 2026
Shows: issue-tracker feature request on vendor repo confirming the problem from a non-community source
A 'Feature Request: Shared Team Memory for Claude Code' issue states that Claude Code's memory system is individual-only and that context does not transfer at the agent level, so humans must manually reconstruct or relay it — described as slow, lossy and a major bottleneck for teams. This is direct issue-tracker corroboration of the candidate's core problem (agent knowledge trapped per-tool, copied by hand).
SupportsDEV Community articles on shared memory over MCP across Claude Code/Cursor/Codex
Shows: practitioner write-ups showing the cross-tool sharing workflow is actively sought and not solved by naive MCP setups
Multiple 2026 practitioner posts describe the same scenario (debugging in Claude Code, switching to Cursor, context gone) and the fix of one shared MCP store; one post specifically documents that two clients can both report a connected memory server yet still share nothing because of scoping/keying differences. Suggests demand plus a real implementation pitfall the candidate must handle (consistent project/repo scoping across clients).
Weakens the caseGitHub repos: daystar7777/agent-work-mem, awrshift/agent-memory-kit, eddmann/obsidian-mcp, YuNaga224/obsidian-memory-mcp; TensorBlock awesome-mcp-servers memory list · 17 August 2026
Shows: crowded adjacent tooling field (multiple free OSS equivalents)
A curated list plus several repos show many shipped options for markdown-file agent memory and cross-agent handoffs — e.g. agent-work-mem ('persistent shared memory and handoffs across Claude Code, Codex CLI, Cursor, Aider using nothing but markdown'), agent-memory-kit (plain files, session handoffs, Claude Code/Cursor/OpenCode/Codex), and git-backed Obsidian MCP servers. The category is validated but commoditised and largely free.
Weakens the caseGitHub repo / MCP registry listing (basicmachines-co/basic-memory)
Shows: direct competitor: established git/Markdown-backed MCP memory server with hosted upsell
Basic Memory is an existing MCP server storing agent knowledge as plain Markdown files, described as local-first, Obsidian-compatible and git-versionable, usable from Claude Desktop, Claude Code, Cursor and other MCP clients, with a hosted paid tier for sync across devices. Occupies nearly the same position as the proposed product; differentiation would have to rest on the four-verb simplicity, single binary, recipient routing and subscribe verb.
Where the problem was reported
Public posts in which people described this problem, grouped into one problem before research began.
- Show HN: Open Agent Forum – a signed public square for agents · openagentforum.com · 31 August 2026
- Show HN: MaCcyP – coding agents push text to a clipboard manager's Agents view · github.com · 31 August 2026
- Show HN: OzBrain, a shared brain for knowledge between agents and your team · ozbrain.com · 21 August 2026
Looked for, not found
- Searches surfaced issue-tracker, vendor and blog sources but no job/freelance posting showing people paid to manually shuttle agent notes between tools, and no keyword-volume or app-store-review data quantifying demand for an agent note bus. Willingness to pay (versus using a free OSS markdown memory server) is therefore untested; the narrow four-verb, git-native framing remains a hypothesis about what buyers want.
This is a researched opportunity, not a guarantee of commercial success. The evidence level and sources show how much is known; the risks and questions to test show what is not.
Related product opportunities
Chosen for a shared category, customer or problem.
Developer tools
Clear RunwayTeams building LLM agents that act inside CRMs, helpdesks, finance tools and email find that agents which demo well break in production for environmental reasons: the service account is missing a scope, an endpoint behaves differently than documented, or a company name in one system does not match the same company in another.
Developer tools
Launch LaneSolo developers, indie hackers and open source maintainers can ship working software, but once it's live nothing happens.
Developer tools
Explain-Before-Merge: a comprehension gate for AI-written diffsDevelopers who ship most of their code through agents like Claude Code, Cursor or Copilot review diffs for whether they 'look right' rather than for whether they understand them.
Developer tools
Flight Deck: a worktree-per-agent control panel for Claude CodeDevelopers who try to run several AI coding agent sessions at once find that nothing manages the mechanics.
Finding and judging opportunities like this one
The method behind this idea, written up as guides you can apply to your own.
- How to find product ideas worth building
Find product ideas by starting from problems people describe in their own work, not from brainstorms. A practical method with real examples, from the research behind Daily Product Idea.
- How to evaluate a product idea before you build it
Evaluate a product idea by scoring the evidence rather than your enthusiasm: six dimensions, a written reason for each score, the assumptions it rests on and the cheapest test to run first.
- How to validate a product idea before building it
Validate a product idea with evidence of what customers do, not what they say: find the assumption that would kill it, run the cheapest test that can fail, and set the pass mark first.